Thanks to Lola
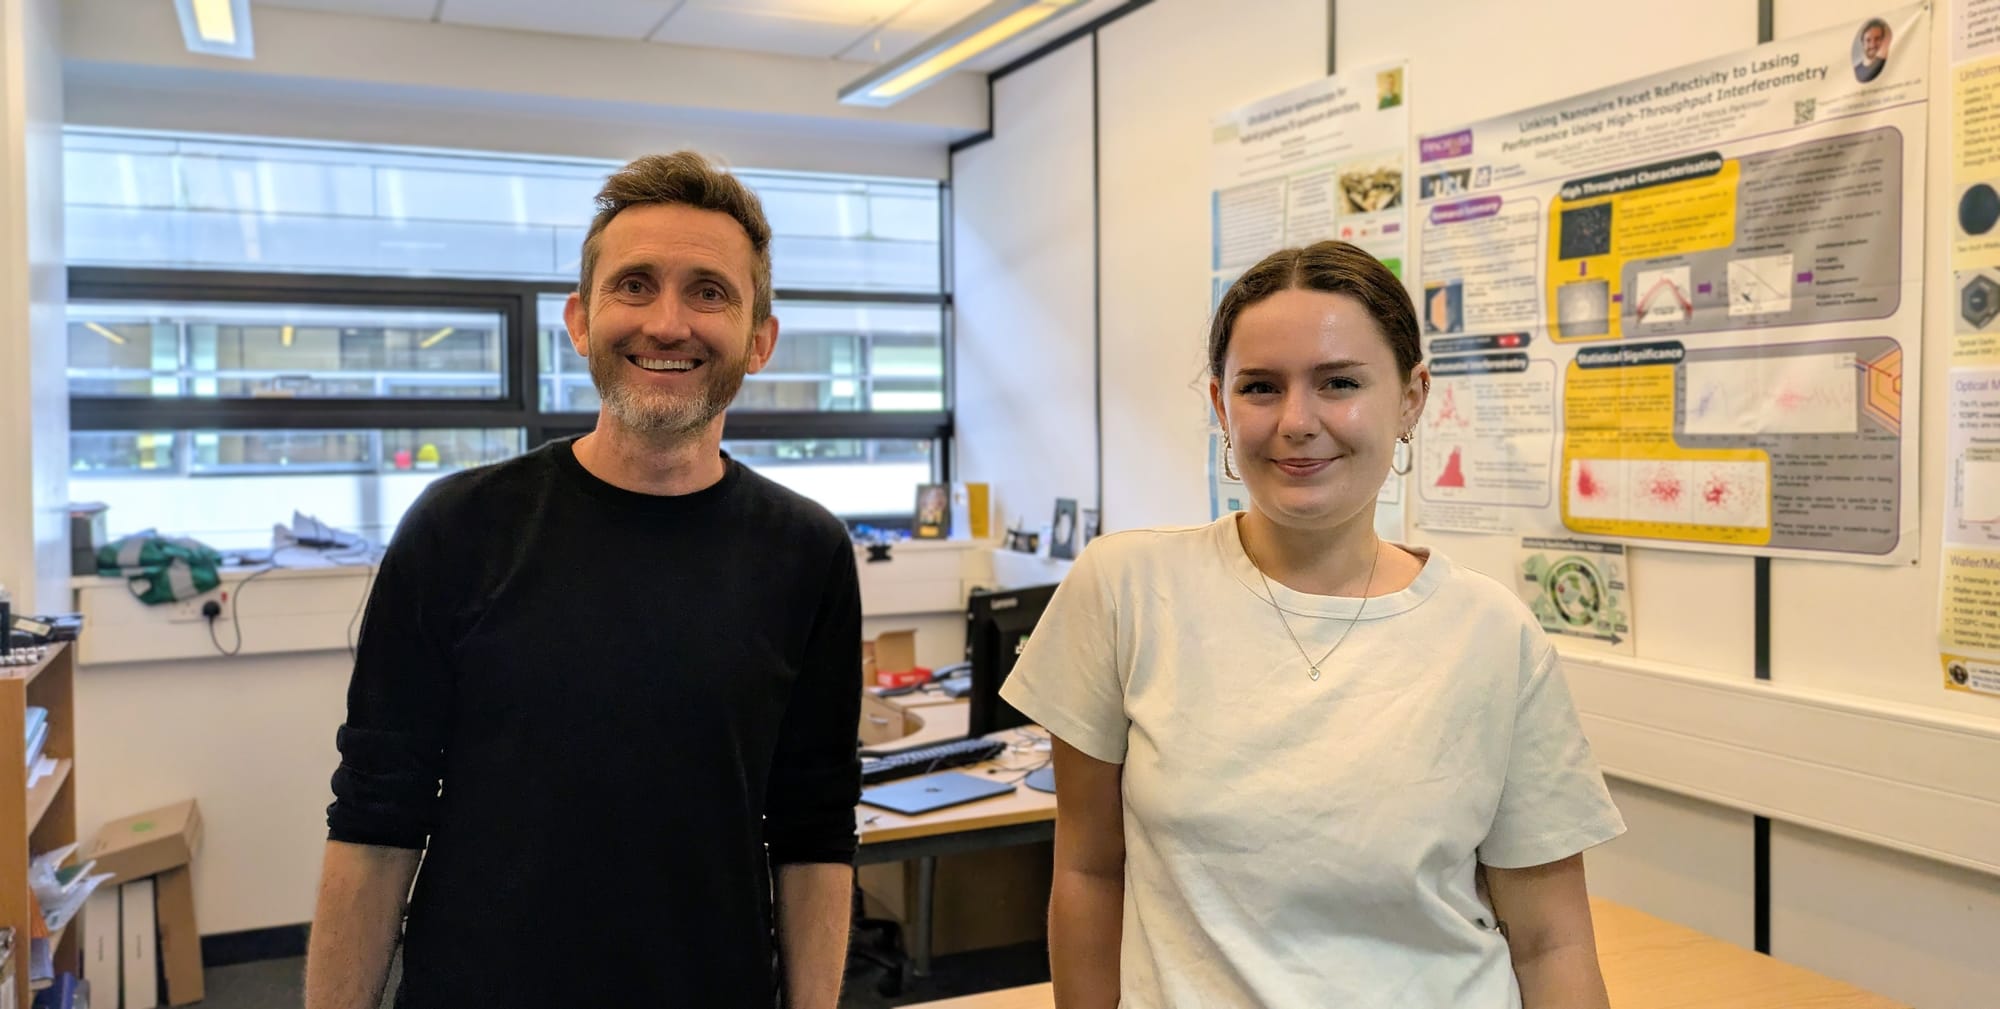
A huge thanks to Dolores Mortimer, summer intern this year, who automated the collection of over 4000 identifiers (ORCID, openAlex, Scopus, UKRI GtR etc) so we could change the question from 'find and tell us your data' to a quick 'are these correct'.
The easy plan: Let's ask academics for a suite of online research identifiers to keep our systems up to date!
The (perhaps obvious) reality: Is data-collection an efficient use of researcher time?
A huge thanks to Dolores Mortimer, summer intern this year, who automated the collection of over 4000 identifiers (ORCID, openAlex, Scopus, UKRI GtR etc) so we could change the question from 'find and tell us your data' to a quick 'are these correct'. Around 170 were wrong and 190 were stale - 9% identifier errors spread over 20% of people, reducing staff data collection time by 10x. Median academic time taken - 5 minutes 40 seconds.
A question that researchers weren't incentivised to answer turned into a paid project that ended up giving far better data. Next step - building tools on our data to engineer serendipity 🚀